Floating-Point Reproducibility
Floating-point reproducibility is a correctness property of the collective offload, not only a numerical-analysis detail. In an in-network collective, the effective reduction order can be affected by packet arrival time, VOQ arbitration, backpressure, egress scheduling, tree shape, and rank-to-port placement. This is a problem for IEEE-style floating-point addition: floating-point addition is rounded after each operation and is therefore not associative.
PRISM studies this problem at the packet-processing boundary. The goal is not to make a whole distributed application deterministic by itself. Local computation, tensor partitioning, compiler choices, GPU kernels, and host-side reduction fragments may still introduce nondeterminism before packets reach the switch. The narrower question is:
PRISM reproducibility question
Given the same Collective Operation identity and arithmetic descriptor, the same rank contributions, and the same exception policy, can a switch-like RTL datapath produce the same final floating-point bit pattern independently of packet timing and arbitration order?
This matters for debugging, regression testing, numerical validation, checkpoint/restart workflows, and scientific or safety-critical workloads where bitwise differences make failures hard to reproduce. It also matters operationally: in a real cluster, the same job may be launched with the same number of ranks but mapped onto different nodes, leaf ports, or aggregation paths.
Candidate strategies
PRISM exposes reproducibility as a design space rather than as a single hard-coded arithmetic choice.
| Strategy | Datapath idea | Reproducibility guarantee | Main cost |
|---|---|---|---|
| FP32_ARRIVAL | Accumulate admissible operands in arrival order. | None beyond a particular execution order. | FP32 state and dependent-update scheduling. |
| KULISCH_FIXED | Convert each finite input into an exact fixed-point deposit in the configured accumulator; round once at the end. | Order-independent exact finite summation before final rounding when the configured width is sufficient. | Wide accumulator state, banking, carry management, final normalization, exception policy. |
AUTO is a separate wire policy: it chooses a lossless representation for a value that the selected accumulator has already produced.
flowchart LR
    S{Accumulator profile}

    S -->|FP32_ARRIVAL| B[Arrival-order FP32 add]
    B --> O1[Order-dependent]

    S -->|KULISCH_FIXED| E[Decode sign, exponent, significand]
    E --> F[Exact fixed-point deposit]
    F --> G[Normalize and round once]
    G --> O3[Order-independent finite sum]
FP32 accumulation rounds each addition in admission order. A superaccumulator removes order as a numerical variable for finite sums within its configured bound.
Node-local versus global exactness
This guarantee applies to the operands merged by one accumulator. In a multi-level tree, serializing an exact local partial to FP32 rounds at that hop. Global, tree-independent exactness requires a lossless partial-state representation. PRISM can transport a partial in a lossless Kulisch representation when its configured arithmetic and partial policies allow it.
Why try superaccumulators now?
In-network collective offload is used in production. SHARP brought aggregation trees into HPC and AI fabrics12, and SwitchML showed that aggregating model updates in the network speeds up distributed training3.
Accelerators rely on mixed precision. Narrow formats such as FP8 E4M3 and E5M2 cut traffic and compute, but they are usually acceptable only because accumulation happens in a wider or more stable format4. The semantics of the accumulator is part of the accuracy of the system.
Programmable switch pipelines were built for packet processing, not for application floating-point arithmetic, and FPISA documents the cost of working around that5. A dedicated FPGA datapath measures the function directly.
The hardware question is quantitative: where the Pareto frontier lies between an FP32_ARRIVAL path and a superaccumulator in area, BRAM/URAM, banking, carry handling, initiation interval, Fmax, backpressure and the latency of the final rounding.
Superaccumulator semantics
For a finite binary floating-point input, the reducer decodes:
where \(p\) is the significand precision including the hidden bit, \(M\) is the integer significand, and \(e\) is the unbiased exponent. Subnormal values are also exact multiples of the smallest subnormal unit:
A Kulisch-style scalar-sum accumulator chooses this smallest unit as its fixed-point least significant bit. Each incoming floating-point operand is deposited into the corresponding fixed-point position. Since the intermediate representation is exact integer state, adding two deposits is associative and commutative up to the capacity of the accumulator. The final floating-point result is produced by normalizing the exact integer sum and rounding once according to the selected rounding mode.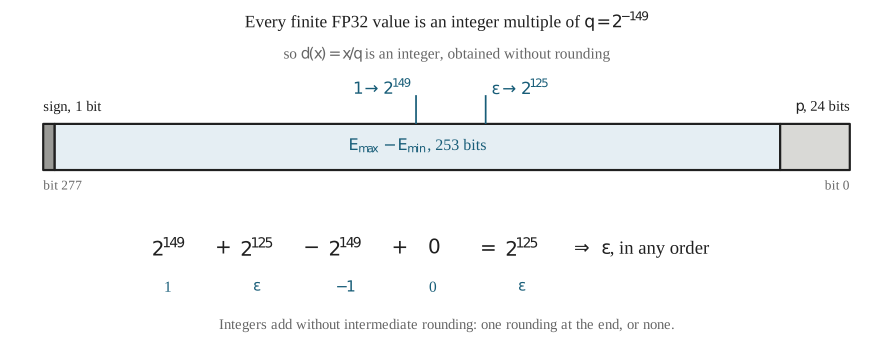
This gives a clean separation between network timing and arithmetic semantics:
Special values must be handled outside the fixed-point datapath. NaNs, infinities, signed zeros, invalid operations, and overflow of the final target format should be tracked with deterministic sideband flags and a documented canonicalization policy. The finite superaccumulator should only receive finite numeric deposits.
Accumulator sizing for scalar reductions
The accumulator width depends on the operation. For PRISM scalar reductions,
the relevant bound is not the dot-product bound. Let:
- \(R\) be the maximum number of participants contributing to one reduction element;
- \(p\) be the significand precision including the hidden bit;
- \(E_{\min}\) be the minimum normal exponent;
- \(E_{\max}\) be the maximum normal exponent.
For exact finite scalar summation including subnormals:
and the signed two's-complement accumulator width is:
The \(+\lceil \log_2 R\rceil\) term is the carry headroom for summing \(R\) same-sign maximum-magnitude operands. The final \(+1\) is the sign bit.
| Input format | \(p\) | \(E_{\min}\) | \(E_{\max}\) | Exact scalar magnitude bits | Signed accumulator for \(R\) participants |
|---|---|---|---|---|---|
| FP8 E4M3FN | 4 | -6 | 8 | 18 | \(19+\lceil\log_2 R\rceil\) |
| FP8 E4M3FNUZ | 4 | -7 | 7 | 18 | \(19+\lceil\log_2 R\rceil\) |
| FP8 E5M2 | 3 | -14 | 15 | 32 | \(33+\lceil\log_2 R\rceil\) |
| FP8 E5M2FNUZ | 3 | -15 | 15 | 33 | \(34+\lceil\log_2 R\rceil\) |
| IEEE FP16 / binary16 | 11 | -14 | 15 | 40 | \(41+\lceil\log_2 R\rceil\) |
| BF16 | 8 | -126 | 127 | 261 | \(262+\lceil\log_2 R\rceil\) |
| IEEE FP32 / binary32 | 24 | -126 | 127 | 277 | \(278+\lceil\log_2 R\rceil\) |
Therefore, a single scalar-reduction accumulator covering FP8, FP16, BF16, and FP32 is dominated by FP32/BF16 exponent range:
For example, with \(R=256\) ranks, an exact signed FP32 scalar-sum accumulator requires:
bits per reduction lane, before adding implementation metadata such as valid bits, exception flags, operation tags, contribution bitmaps, or bank-selection state.
Do not confuse scalar reduction with dot product
The wider Kulisch dot-product bound applies to:
not to a normal collective sum of already-computed floating-point values. For a dot product, the exact product range roughly doubles the exponent span, giving:
and:
For FP32 dot-product accumulation this gives \(555+\lceil\log_2 N\rceil\) signed bits. That number is appropriate for an exact MAC engine, not for a scalar ALLREDUCE-style sum.
Parallelism and line rate
For \(b_d\) bits per element, \(L_d\) lanes, clock \(f\), and initiation interval \(II_d\):
At 250 MHz and \(II=1\), FP32 needs 13 active lanes for 100 Gbit/s, FP16/BF16 need 25, and INT8 needs 50. The current core keeps TILE_ELEMENTS=16 and forms an issue group from 1, 2, or 4 tiles. It therefore accepts 16 FP32, 32 FP16/BF16, or 64 INT8 elements per cycle, equal to 128 Gbit/s in every case. Output conversion can impose a second limit: 64 INT8 inputs converted to FP32 produce 2048 result bits per cycle.
Why not only preserve the FP32 order?
Preserving a strict floating-point order is a valid baseline, but it is not equivalent to exact accumulation.
A deterministic FP32 reducer still rounds after every addition. It can make the result repeatable, but the selected order becomes part of the numerical algorithm. A different rank count, different chunking, or different local partial sums can still change the result. In contrast, an exact finite accumulator makes the reduction independent of the order in which finite operands are deposited; only the final rounding step remains.
Preserving order can also fight the purpose of in-network computing. If reproducibility is achieved by gathering operands to a root, serializing the reduction, or forwarding intermediate FP32 accumulators across endpoints, the design may reintroduce communication and synchronization overhead that INC was meant to avoid. A superaccumulator can retain exact state within each node; between nodes, AUTO uses a narrow partial when it is lossless and a wider one when necessary.
PRISM therefore compares two accumulator policies:
- FP32_ARRIVAL, the FP32 admission-order baseline.
- KULISCH_FIXED, which retains exact finite sums; partials can use a lossless wire format.
Each profile defines both its state representation and contributor-update rule. The exact policy uses the Kulisch width configured for the operation. Admission derives the required width from the input domain and maximum original terms; an insufficient width cannot be admitted as exact. A future dot-product operation requires the wider product bound rather than the scalar SUM bound.
Expected outcome
The expected contribution is an implementation-level measurement of the trade-off:
The question is not whether a superaccumulator is always preferable, but under which conditions it can be integrated without losing line-rate operation.
NVIDIA, Scalable Hierarchical Aggregation and Reduction Protocol (SHARP) documentation. SHARP is described as offloading MPI and machine-learning collective operations from CPUs and GPUs to the network. https://docs.nvidia.com/networking/display/sharpv300 ↩
NVIDIA Developer Blog, Advancing Performance with NVIDIA SHARP In-Network Computing. The post describes SHARP as switch-ASIC in-network computing for collective communication. https://developer.nvidia.com/blog/advancing-performance-with-nvidia-sharp-in-network-computing/ ↩
Sapio et al., Scaling Distributed Machine Learning with In-Network Aggregation, NSDI 2021. https://www.usenix.org/conference/nsdi21/presentation/sapio ↩
NVIDIA Transformer Engine documentation, Using FP8 and FP4 with Transformer Engine. https://docs.nvidia.com/deeplearning/transformer-engine/user-guide/examples/fp8_primer.html ↩
Yuan et al., Unlocking the Power of Inline Floating-Point Operations on Programmable Switches, NSDI 2022. https://www.usenix.org/system/files/nsdi22-paper-yuan.pdf ↩